Translating the full HTML, visible text only, structure and markup preserved.Writing the full English translation carefully, then emitting the complete HTML.
Research brief · XiaoHu Explains
Two API settings took GPT-5.6 Sol from 13.3% to 38.3% on ARC-AGI-3
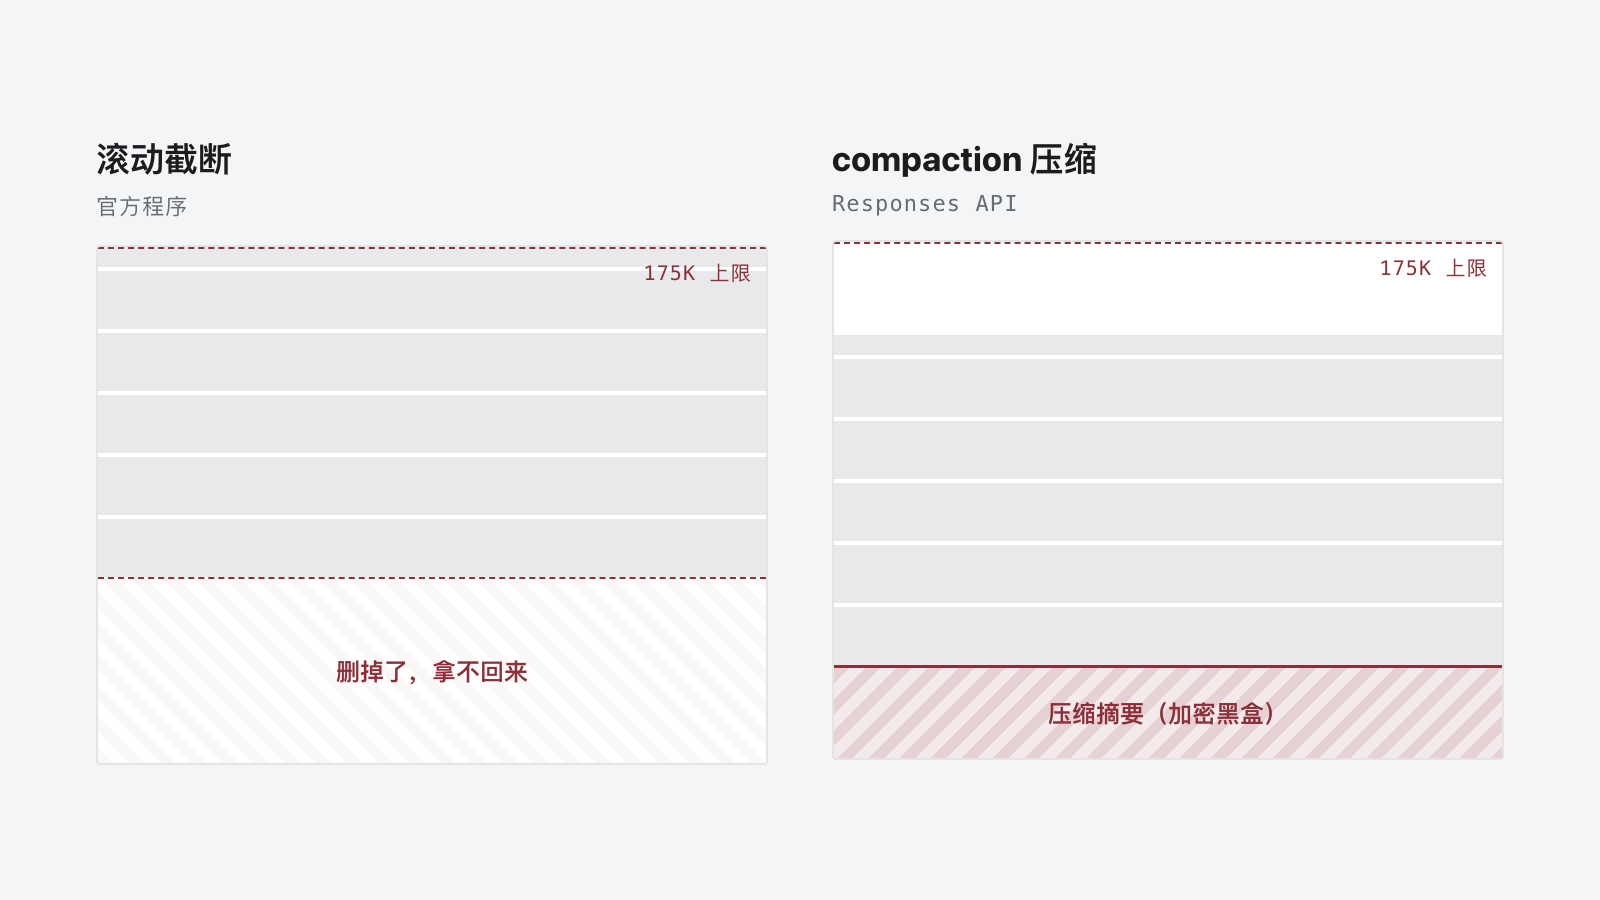
Same model. Different harness: keep private reasoning, and compact instead of deleting. Output tokens per game fell to about one-sixth.
⚑ Source material is OpenAI's official blog about its own model and APIs. The 38.3% result is OpenAI's self-run score. The only numbers independently verified by ARC Prize are 13.33% and 7.78% under the official harness—keep that boundary in mind when reading. Extra sources we checked ourselves are listed at the end.
Opening
Same model, same tasks, nearly 3× the score
OpenAI published a concrete postmortem: same GPT-5.6 Sol, same benchmark tasks, only two API settings turned on—score from 13.3% to 38.3%, and output tokens per game down to about one-sixth. If you run any multi-step job over the API, those two switches decide both score and bill.
Primary source and reference
- OpenAI Original publisher