Research Breakdown · XiaoHu Explains
Databricks tested every model and harness on its own multi-million-line codebase — here's what's actually worth the money
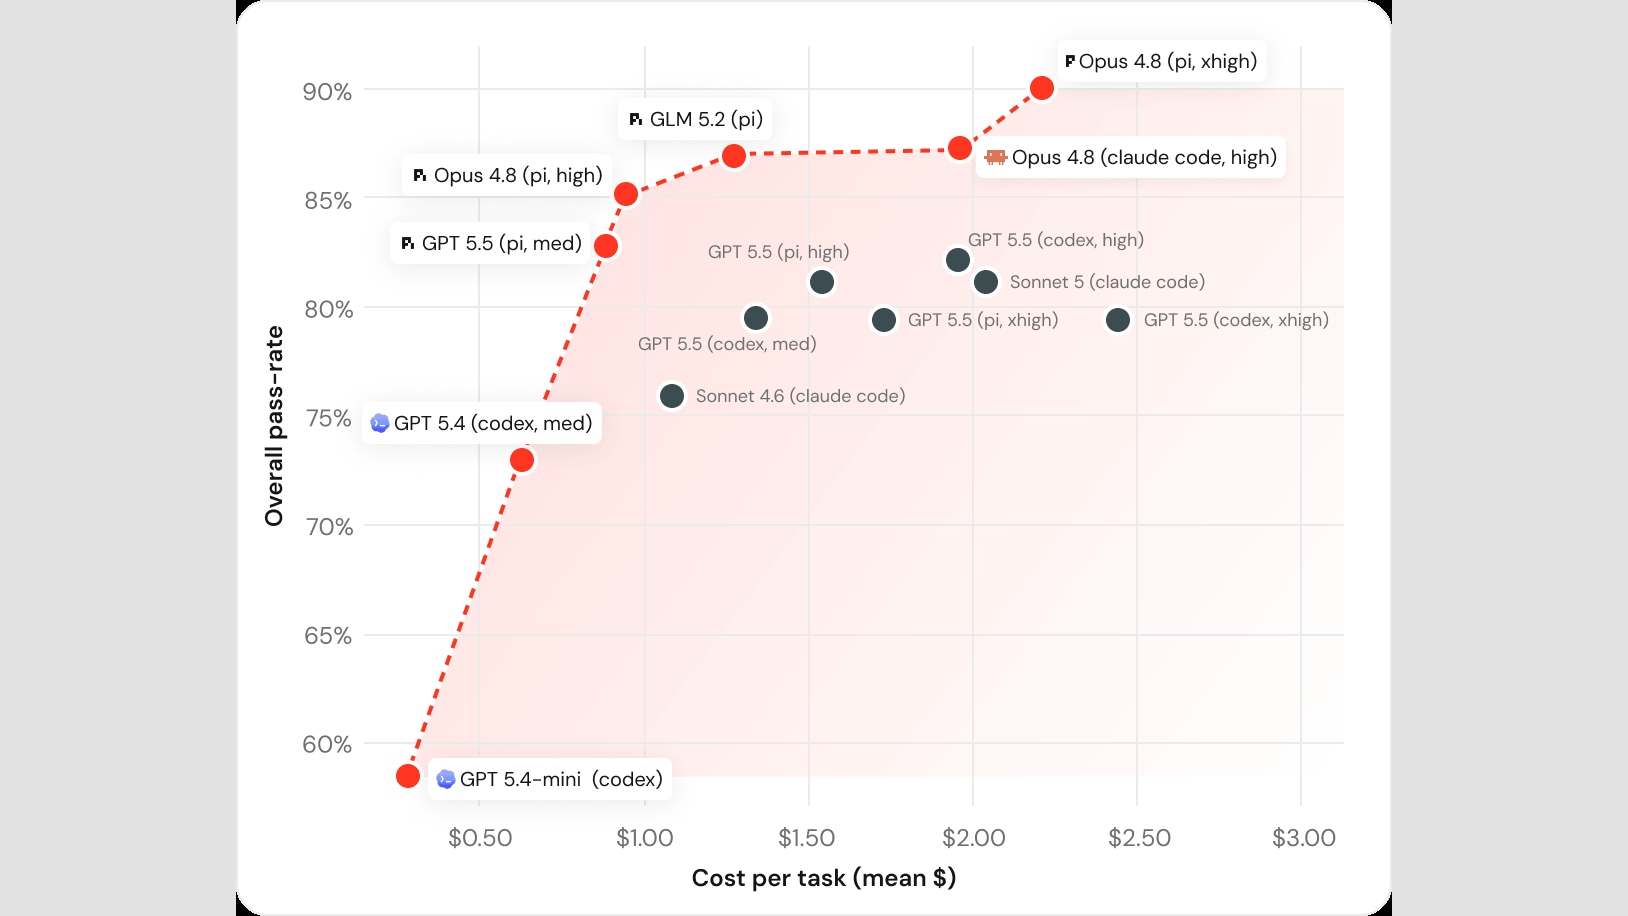
Swap the harness under the same model and the cost can double. The open-source GLM 5.2 ties Opus 4.8 on quality — for 30 percent less per task. The test questions were adapted from Databricks' own merged PRs, so nothing shows up in a search engine.
⚑This is an internal test report Databricks published on its own blog — all the data was collected and graded by Databricks itself. Omnigent and Unity AI Gateway, mentioned throughout, are its own products, and the close teases a follow-up on its own smart routing. Read the numbers with that in mind; we won't flag it again at every turn.
This is an internal benchmark Databricks published itself, built to answer one question: in a multi-million-line codebase, which AI coding agent — meaning which model-plus-harness combination — actually delivers the best value and the smoothest experience. It went up on July 8; the five authors include CTO and Spark creator Matei Zaharia.
Primary source and reference
- Databricks Original publisher